
PostgreSQL backends for LexiSharp: lexical full-text search on tsvector, ANN on pgvector, sparse retrieval, fuzzy search on pg_trgm, and true Okapi BM25 on the ParadeDB pg_search (Tantivy) extension.
Install
| Product | Versions |
|---|---|
| .NET |
README
LexiSharp




A composable information retrieval toolkit for .NET — build, measure and inspect search pipelines, from lexical BM25 to hybrid and reranked retrieval.
Index, retrieve, rank and judge a search pipeline: an in-memory inverted index, four ranking strategies and their BM25 variants, rank fusion, reranking, optional PostgreSQL backends, and model-agnostic seams for dense, learned-sparse and neural scoring — the models stay in your application. The core package references no NuGet package at all.
📖 Full documentation → — the guide, the
reference, and every measurement with the command that reproduces it. This README is the
short version; the details live in docs/.
Install
dotnet add package LexiSharp # the core: index, scorers, engines, decorators — no dependencies
net10.0, MIT. Optional: LexiSharp.MessagePack (binary index persistence),
LexiSharp.AspNetCore (a GET /search minimal-API endpoint), LexiSharp.Postgres
(lexical, vector, sparse, fuzzy and true BM25 backends).
Use it
using LexiSharp.Core;
using LexiSharp.Indexing;
using LexiSharp.Ranking;

ITextSearchEngine engine = new RankedTextSearchEngine(
    new InMemoryTextIndex(),
    new Bm25Scorer());

engine.Index(new[]
{
    new SearchDocument("1", "The search engine uses BM25 to rank the results"),
    new SearchDocument("2", "TF-IDF is a classic method of textual search"),
    new SearchDocument("3", "Italian cuisine is renowned in Rome"),
});

foreach (var result in engine.Search("textual search"))
    Console.WriteLine($"{result.DocumentId} - {result.Score:0.###}: {result.Document.Text}");
LexiSharpIndex<T> is the typed facade over the same engine if you would rather hand it
your own objects — see Getting started.
See it running
dotnet run --project samples/LexiSharp.Demo # → http://localhost:5000
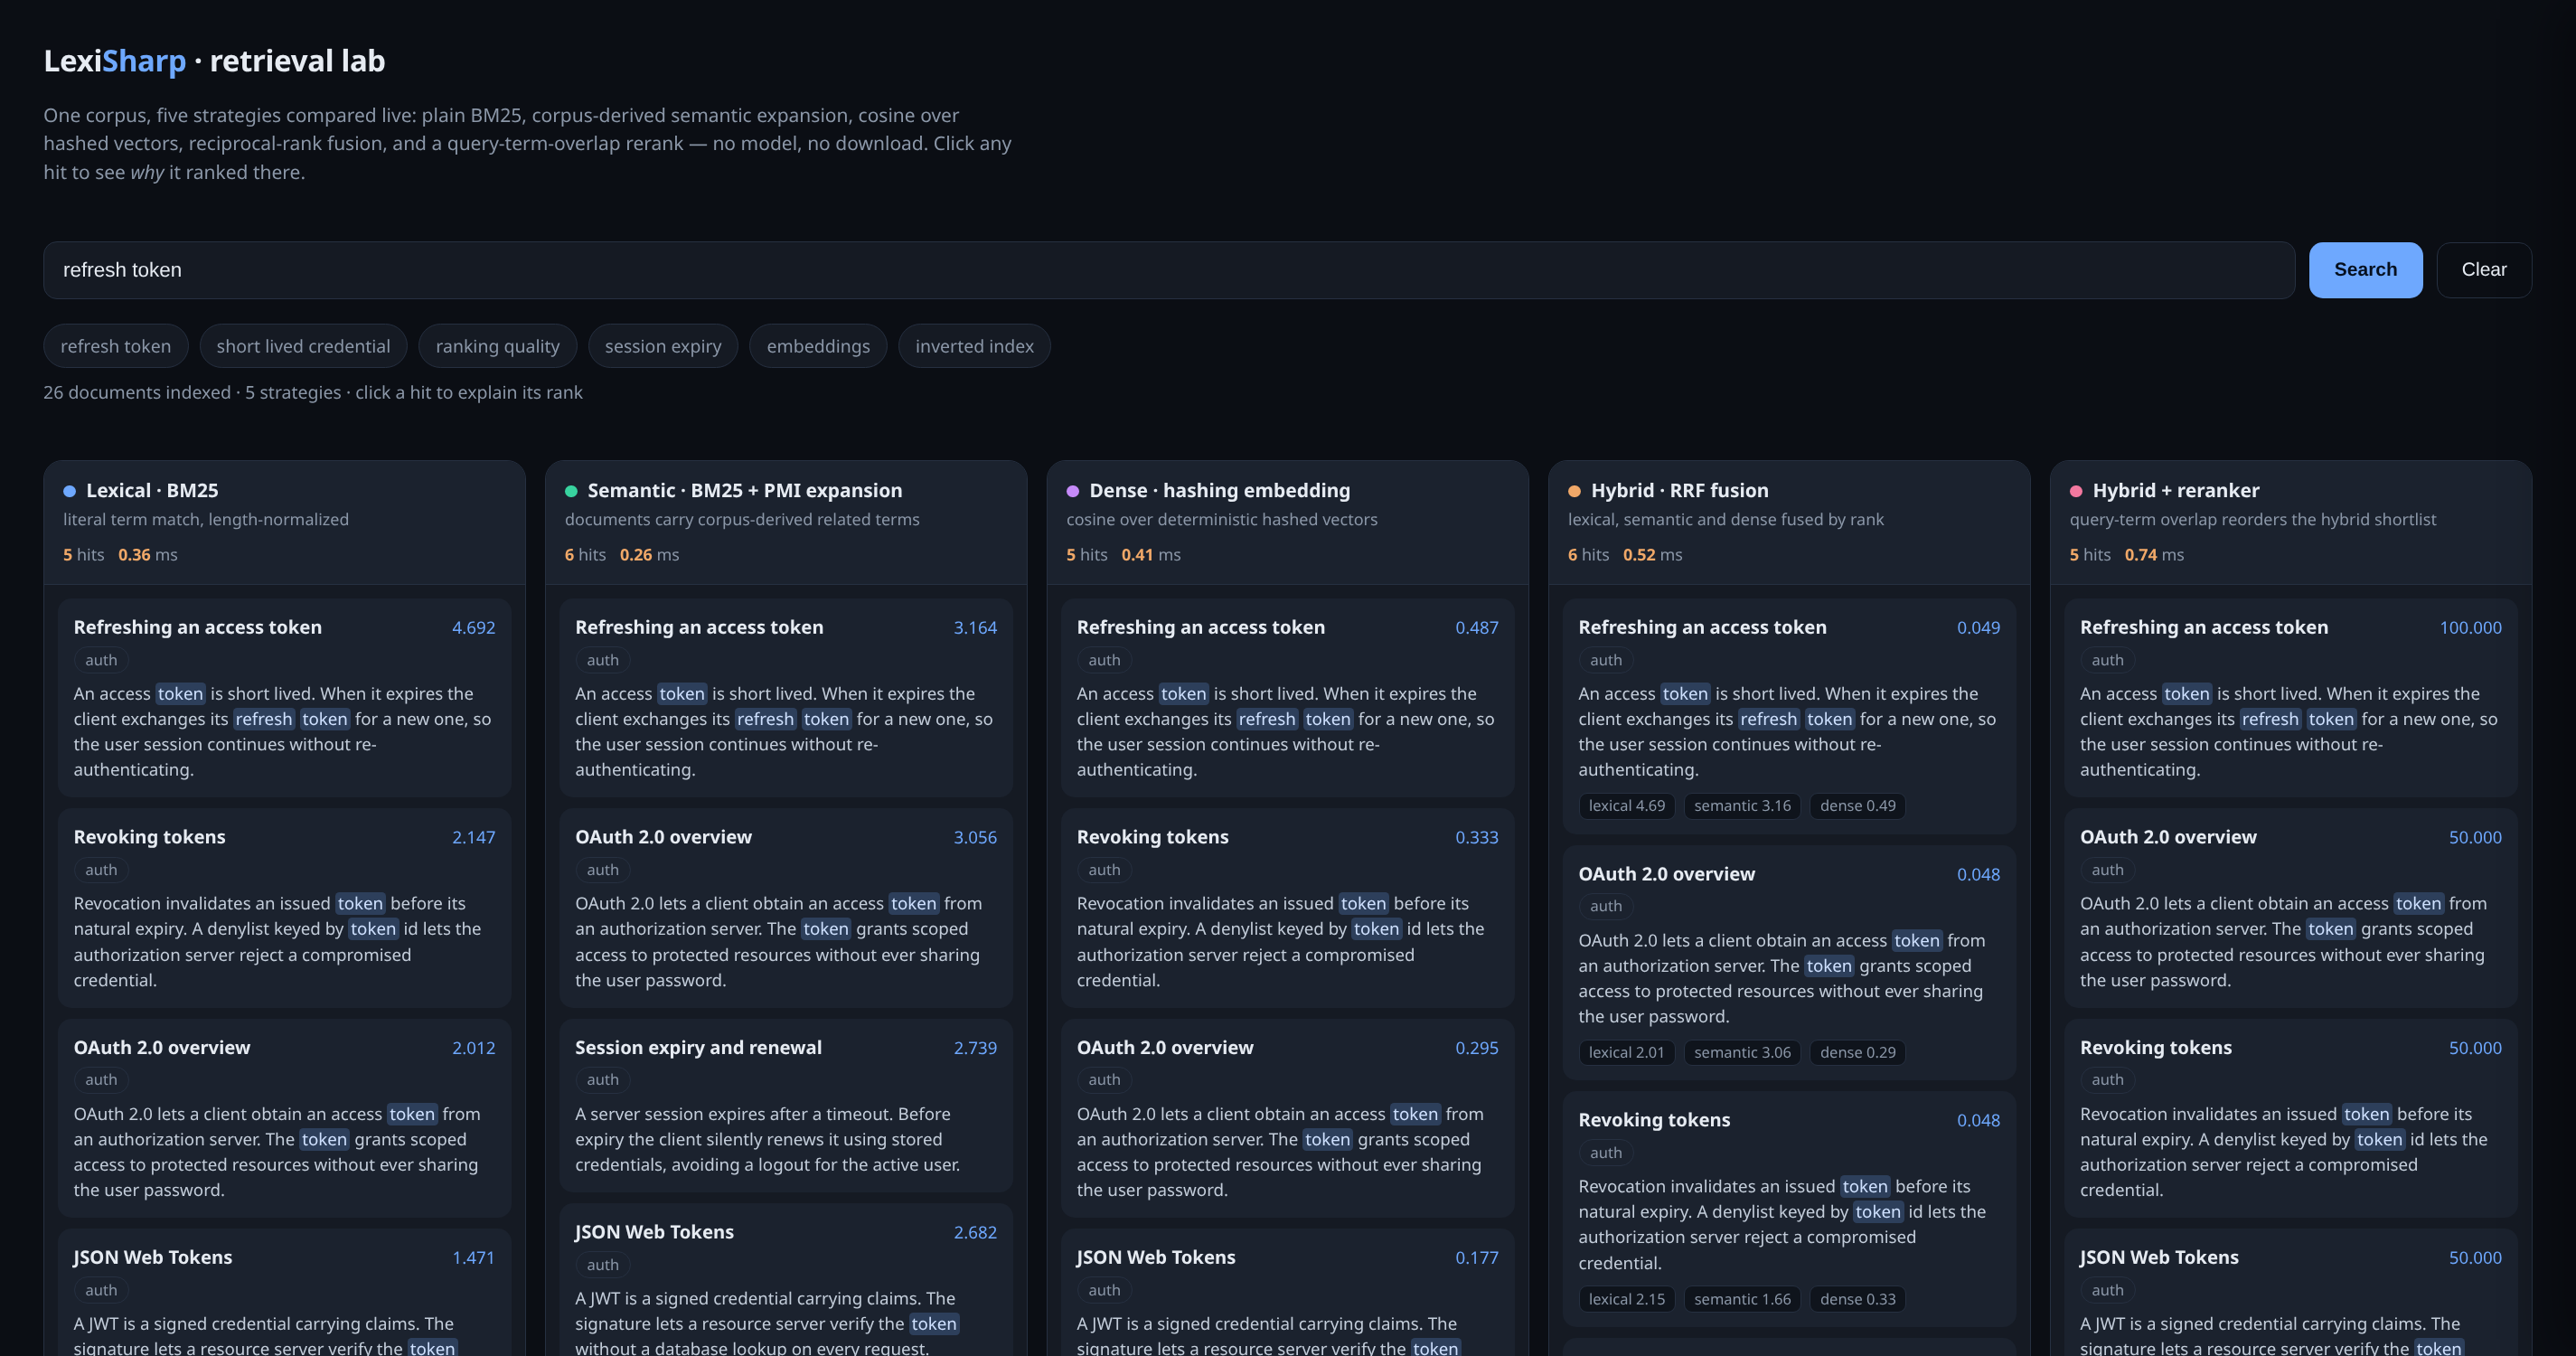
Five retrieval strategies over one corpus, compared live — BM25, corpus-derived semantic expansion, dense hashing embeddings, RRF fusion and a term-overlap rerank — with per-lane latency, highlighting and a click-through "why did this rank here?" panel. No model, no external service.
What it does
- An inverted index — term positions, document frequencies, corpus statistics,
incremental
Add/Remove, and named text fields per document (indexing). - Four scorers and their variants — BM25, TF-IDF, query likelihood, a boolean filter,
plus BM25+, BM25L and field-weighted BM25F, each with a per-term
IScoreExplainerbreakdown (ranking).- The usual query operators — metadata filters, phrases, prefix and fuzzy terms, synonyms, facets, highlighting, pagination (querying). - Composable pipelines — rerankers (MMR, cascade, cross-encoder, MaxSim), hybrid federation with five merge strategies, cost-based and intent-based routing (pipelines).
- Embeddings as seams, not as features —
IEmbeddingProvider,ISparseEmbeddingProvider,ITokenEmbeddingProvider,ICrossEncoderScorer: you supply the model, the library wires the retrieval.HashingEmbeddingProvidermakes the whole stack testable with no model at all (embeddings). - Persistence and scale as separate packages — MessagePack, ASP.NET Core, and
PostgreSQL engines over
tsvector,pgvector,sparsevec,pg_trgmand ParadeDB's Tantivy BM25 (backends). - Instrumentation —
SearchTracewalks one ranking back stage by stage;RetrievalTelemetrymeasures every search in production;RetrievalAgreementAnalyzersays whether a fused page was agreed on or insisted upon (observability). - The instruments to distrust your own ranking — IR metrics, four parameter tuners (BM25, BM25F, BM25+, BM25L) that report whether the extra knob earned its place, a benchmark CLI over your corpus, and a per-query diff that names which queries a change rescued and which it lost (evaluation).
What is measured, and what is not
A library that quotes only its good numbers is not worth reading twice. Every figure below is reproducible with a command on the evaluation page.
- Against published baselines. On three public BEIR corpora, BM25 reaches nDCG@10 0.308 (NFCorpus), 0.662 (SciFact) and 0.289 (ArguAna) against BEIR's published 0.325 / 0.665 / 0.315 — 5.2 %, 0.5 % and 8.3 % below. Corpora are md5-verified on download.
- The composed stack, where it is measured. On NFCorpus the dense lane alone lands at BM25 level (0.304), BM25+dense RRF reaches 0.333 and a cross-encoder rerank 0.346. Those lanes are the only ones that use a real model, it comes from the harness rather than the library, and this is the one corpus where all of them run.
- Zero runtime dependencies in the core. Inverted index, BM25, every scorer and every decorator are BCL only.
- Tests, not assertions. Everything documented is covered by the xUnit suite; the
Postgres and ParadeDB integration tests run live on every build and self-skip without
POSTGRES_TEST_CONNECTION. Ranking outputs are gated by a committed golden master, so a change to scoring shows up as a reviewable diff. - Named, not glossed over.
SearchTrace's time cost is unmeasured (its allocation is pinned; no timing is quoted because the baseline itself varied 2.3× between identical runs). The SQL backends' retrieval quality is unmeasured — the BEIR harness runs the in-memory engines. The learned-sparse lane has no model wired into that harness, and corpus-derived expansion is a measured loss where it has been measured (0.8469 against BM25's 0.8751 on the reference corpus). BM25F has no measured win over a tuned BM25, and proximity hurts at full strength. BM25+ and BM25L, tuned on their own δ, tie a tuned BM25 on the reference corpus and NFCorpus and edge it by 0.002–0.004 on SciFact — an in-sample margin on the queries that chose it, so an upper bound rather than a result. ArguAna is untuned and is their worst showing anywhere: 0.243 and 0.249 against BM25's 0.289 at a fixed δ, with no δ-tuned row to say whether tuning closes it. Not every combination of engine, scorer, reranker and merger is exercised by a test.- Version 0.4.0, one maintainer. The public API may still change between minor versions — pin a version.
Full scope and limits: docs/reference.md.
Documentation
Hosted at https://manuc66.github.io/LexiSharp/ (published from docs/).
| Page | What is in it |
|---|---|
| Getting started | the engine in three lines, the typed facade, document loaders, an HTTP endpoint, the demo |
| Indexing | the index and its statistics, named fields, the tokenizer and stemming, persistence |
| Querying | filters, pagination, phrases, highlighting, prefix & fuzzy, synonyms, facets |
| Ranking | the scorers, BM25+/BM25L and their δ tuners, BM25F, boosting, proximity, explanations — with their measurements |
| Pipelines | rerankers, hybrid fusion, routing |
| Embeddings and expansion | dense, learned-sparse, corpus-derived expansion |
| Text analysis | similarity, keyword extraction, classification |
| Backends | PostgreSQL and ParadeDB engines, what the integration tests cover |
| Observability | traces, production telemetry, source agreement, score confidence |
| Evaluation | BEIR results, IR metrics, the benchmark CLI, per-query diffs, tuning |
| Benchmarks | allocations and timings, with the machine and the command |
| Reference | packages, architecture, conventions, limits, build and test |
| SPLADE guide | writing a consumer-side ISparseEmbeddingProvider |
Build & test
dotnet build LexiSharp.slnx
dotnet test  tests/LexiSharp.Tests                # xUnit suite; Postgres suites need POSTGRES_TEST_CONNECTION
dotnet run  --project bench/LexiSharp.Benchmarks  # BenchmarkDotNet (published numbers: docs/benchmarks.md)
dotnet run  --project bench/LexiSharp.Cli -c Release -- verify bench/reference-corpus/corpus \
    --queries bench/reference-corpus/queries.json --qrels bench/reference-corpus/qrels.tsv \
    --configs bm25,bm25-semantic,bm25f,bm25+,bm25l,bm25-proximity-full --top-k 5 \
    --against bench/reference-corpus/golden/rankings.txt
License
MIT — see LICENSE. The ParadeDB pg_search extension used by the BM25 backend is
licensed separately, under AGPL-3.
Changes from Previous Version
Adoption Assessment
Assess this package against its supported frameworks, license, maintenance signals and dependency graph before making it a project standard.
Related Guides & Workflows
Learn how to evaluate, integrate, or audit this package in your .NET project.